

Diagnose Slow PostgreSQL Queries with EXPLAIN
Why Slow PostgreSQL Queries Need Evidence
A slow PostgreSQL query is often blamed on the database before its actual bottleneck is measured. The delay may come from a sequential scan, an inefficient join, sorting a large result set, disk access, lock waits, or simply returning far more rows than the application needs. EXPLAIN ANALYZE turns that guesswork into an execution plan that shows how PostgreSQL actually ran the statement.
For example, a query that normally returns 20 customer records may scan 4 million rows because the filtering column lacks a useful index. An application developer might first increase the connection pool or add caching, but those changes do not remove the underlying work. Start by measuring the query in a representative environment, recording the SQL text, parameters, returned row count, and execution time.
EXPLAIN Versus EXPLAIN ANALYZE
EXPLAIN shows PostgreSQL's planned strategy without executing the query. It reports estimated startup cost, total cost, estimated rows, and estimated row width. EXPLAIN ANALYZE executes the statement and adds actual startup time, total time, actual row counts, and loop counts for each plan node. The comparison between estimates and reality is one of the most useful parts of the output.
Use a statement such as EXPLAIN (ANALYZE, BUFFERS) SELECT id, email FROM users WHERE organization_id = 42; on a read-only query when investigating performance. Be careful with INSERT, UPDATE, and DELETE: EXPLAIN ANALYZE performs the operation unless it is wrapped in a transaction that you roll back. In production, prefer a safe replica or a controlled transaction, because analyzing a write can change data and add load.
Reading the Main Plan Nodes
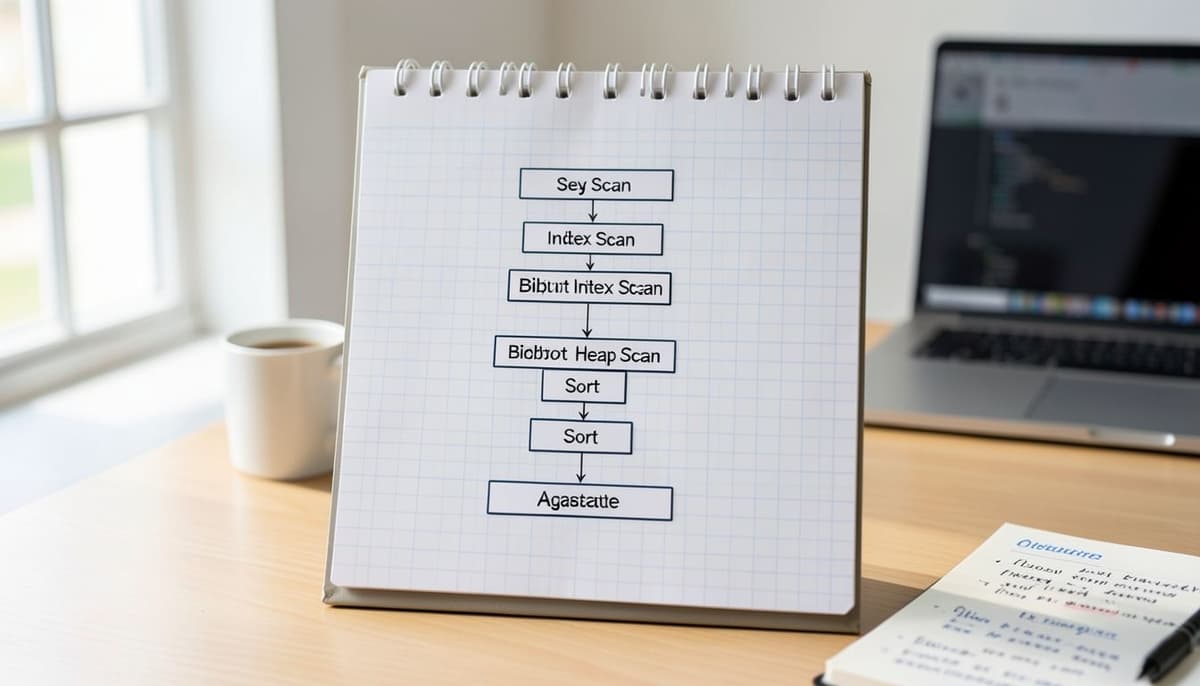
Read an execution plan from the bottom upward because lower nodes produce rows for the nodes above them. A Seq Scan reads a table sequentially, while an Index Scan uses an index to locate matching rows. A Bitmap Index Scan followed by a Bitmap Heap Scan can be effective when many scattered rows match. A Sort orders rows, and an Aggregate calculates values such as COUNT or SUM.
The key question is not whether a node looks complex, but how much work it performs. A sequential scan over a 500-row table may be faster than using an index, while the same scan over 50 million rows deserves attention. Pay particular attention to nodes with high actual time, large row counts, many loops, or a large difference between estimated rows and actual rows.
Spotting Bad Row Estimates
PostgreSQL chooses a plan using table statistics. If it estimates 10 rows but actually processes 100,000, it may choose a nested loop join or an index strategy that becomes expensive at runtime. This mismatch often occurs after large data changes, with correlated columns, highly uneven value distributions, or predicates that statistics do not describe well.
Run ANALYZE on the affected table to refresh statistics, or use VACUUM (ANALYZE) when routine maintenance is also needed. For a column with a skewed distribution, increasing its statistics target can improve estimates, although it also increases analysis work and catalog storage. After changing statistics, run EXPLAIN ANALYZE again and confirm that the plan and measured behavior improved rather than assuming the estimate alone solved the issue.
Finding Missing or Ineffective Indexes
An index can help when a query repeatedly filters, joins, or orders by a selective column. For example, CREATE INDEX ON orders (customer_id, created_at DESC) may support a query that retrieves one customer's newest orders. Column order matters: a multicolumn index beginning with customer_id is generally more useful for customer-specific lookups than one beginning with created_at.
Do not add indexes automatically whenever EXPLAIN shows a sequential scan. Indexes consume disk space, slow writes, and may be ignored when a query returns a large percentage of the table. Check whether the predicate applies a function or cast that prevents a normal index from being used, and consider a functional or partial index only when the query pattern is stable and the maintenance cost is justified.
Investigating Joins, Sorts, and Buffers
Join performance depends on table sizes, join conditions, available indexes, and row estimates. A Nested Loop can be excellent when the outer side is small and the inner side has an efficient index, but it can become very slow when both sides produce thousands of rows. Hash Join and Merge Join have different memory, sorting, and input-order requirements, so compare actual timing and row counts instead of choosing a join type by name.
The BUFFERS option helps distinguish computation from data access. Shared hit blocks came from PostgreSQL's shared buffers or operating-system cache, while shared read blocks required storage reads during execution. A plan reading hundreds of thousands of blocks may need a better filter or index, but a plan with many hits can still be slow because it processes too many rows. Sort nodes that spill to temporary files may also benefit from carefully adjusted work_mem, tested for the specific workload.
Applying and Verifying a Safe Fix
Treat every optimization as a hypothesis. If the plan shows an outdated estimate, refresh statistics; if it scans unnecessary rows, test a more suitable index or rewrite the predicate; if it returns too much data, reduce selected columns or add pagination. Avoid changing several variables at once, because you will not know which change produced the result. Use realistic data volumes and the same parameter patterns that caused the original slowdown.
After making a change, compare execution time, planning time, actual rows, buffer counts, and resource use before and after. A query that falls from 900 milliseconds to 80 milliseconds in a local database may behave differently under concurrent traffic or with a cold cache. Check application logs and connection behavior as well, because slow execution can be confused with queueing, lock contention, network transfer, or time spent serializing a very large result.
Further Reading
Tags :
- Backend Development