



Test Objective and Core Principle
A useful audience test answers one business question at a time. For example: does a broad cold audience acquire qualified customers more efficiently than an interest-based cold audience? That question is interpretable because the audiences are the primary variable. If the audiences also receive different creative, offers, placements, optimization events, or budgets, you cannot confidently attribute the result to targeting.
Prospecting and retargeting must be treated as separate systems. Prospecting reaches people who have not recently interacted with the business, while retargeting reaches people who have demonstrated intent through website visits, product views, lead activity, video engagement, or another defined action. Their conversion rates, costs, messaging needs, and available scale are different. Comparing them as if they were equivalent audiences creates misleading conclusions.
Before launching a test, write a one-sentence hypothesis, the primary success metric, the decision threshold, and the minimum test period. A practical hypothesis could be: broad targeting will produce a lower cost per qualified lead than interest targeting while maintaining an acceptable lead-to-sale rate. This prevents the team from changing the definition of success after seeing early results.
Build a Controlled Test Architecture
Use separate campaigns or clearly separated ad sets when doing so improves budget control and reporting clarity. Within a prospecting test, keep the conversion location, optimization event, attribution setting, geographic market, placements, schedule, offer, and creative package consistent. Give each audience a fair opportunity to spend. If one audience receives significantly more delivery, the comparison may reflect budget allocation rather than audience quality.
Choose the budget method according to the test goal. Ad set-level budgets generally provide more control when equal or deliberately proportional spend is required across test cells. Campaign-level budget optimization can be appropriate after the winner is known, but during an audience test it may direct most spending to one ad set before enough evidence exists for comparison. Meta’s built-in experiment capabilities can also support cleaner allocation when they are available and suitable for the account.
Name each test cell so that its role and variable are obvious in reporting. A practical naming convention should identify funnel stage, market, audience type, optimization event, and test version. The exact wording matters less than consistency. Document launch date, planned end date, audience definition, exclusions, creative IDs, budget, hypothesis, and decision rule in a test log before activation.
Design Cold Prospecting Tests
Start with audience categories that represent meaningfully different strategies. Common prospecting cells include broad targeting within required location and age constraints, an interest or behavior-based audience, and a lookalike audience created from an appropriate first-party source. Avoid testing several interest groups that are nearly identical unless the business question specifically concerns those interests. Minor targeting differences often produce little strategic learning and increase overlap.
Exclude recent customers and the retargeting population from prospecting when the goal is to measure new-customer acquisition. The exclusion window should reflect the sales cycle and campaign purpose. An ecommerce advertiser might exclude recent purchasers for a defined repurchase period, while a high-consideration service may exclude existing leads and customers for longer. Apply equivalent exclusions across every prospecting cell so one audience does not gain an advantage by capturing warmer users.
Use the same creative package across audiences during the initial targeting test. Include enough creative variety to avoid making the entire result depend on one advertisement, but do not assign exclusive concepts to individual cells. If the broad audience receives a strong customer testimonial while the interest audience receives a weak product image, the test measures both audience and creative differences. After identifying a promising audience strategy, run a separate creative test within that strategy.
Be aware that Meta’s audience expansion and automation options can broaden delivery beyond audience suggestions in some campaign setups. Review the targeting controls and delivery behavior available for the selected campaign type before calling a cell a strict interest test. The test documentation should state whether the inputs are hard constraints, audience suggestions, or seed signals used by an automated system.
Design Funnel-Based Retargeting Tests
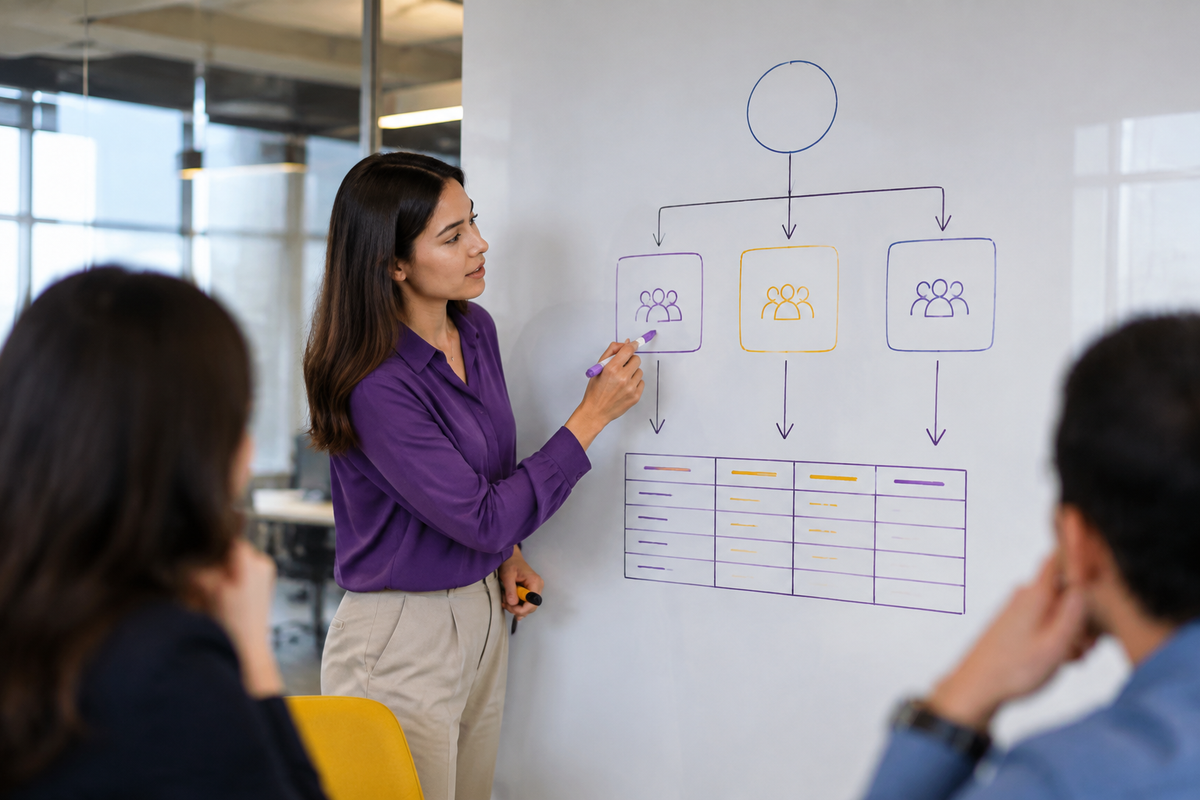
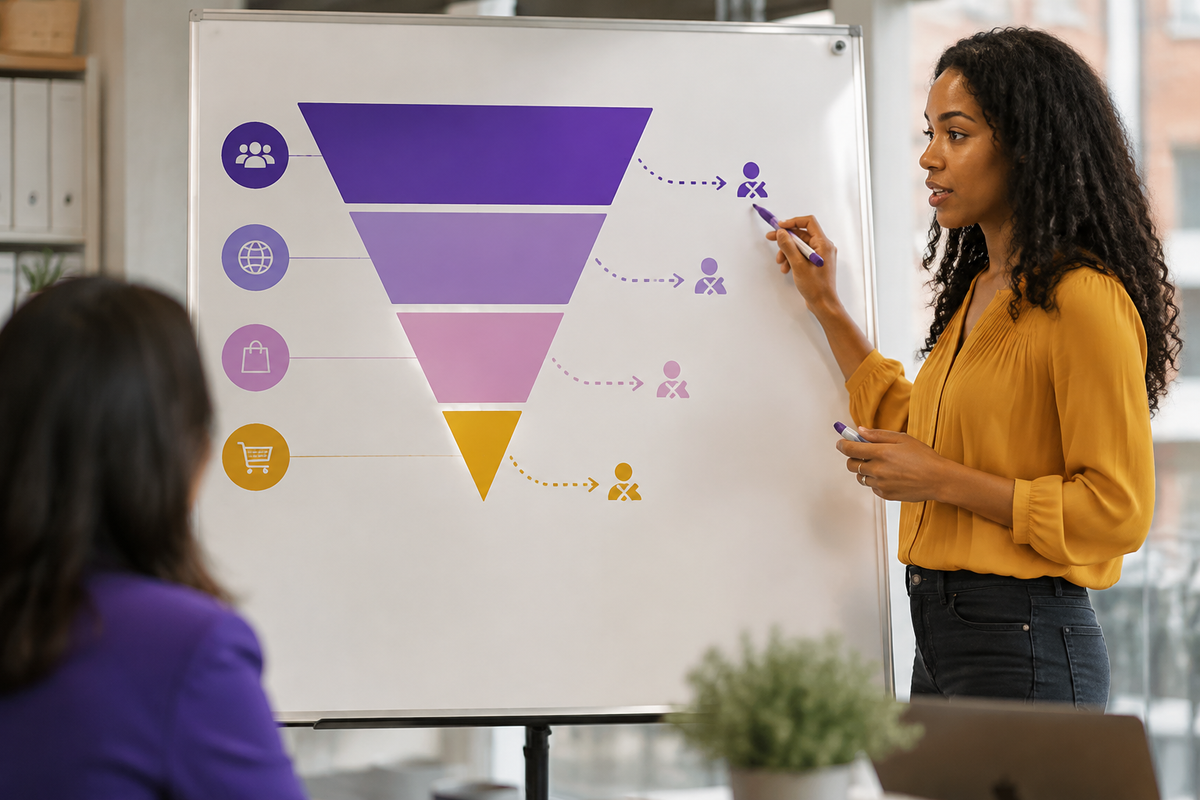
Build retargeting around intent stages rather than placing every warm user into one audience. A practical funnel may separate high-intent users, such as cart starters or pricing-page visitors, from medium-intent users, such as product viewers, and lower-intent engagers, such as video viewers or social profile visitors. Each stage should have a defined lookback window based on the expected buying cycle.
Make the stages mutually exclusive wherever possible. A person who added a product to the cart may also be a website visitor and social engager. If that person qualifies for three ad sets, those ad sets can compete against one another and make stage-level performance difficult to interpret. Use exclusions so the highest-intent segment takes priority, the medium-intent segment excludes the high-intent group, and the lower-intent segment excludes both. Exclude purchasers or completed leads unless the campaign is intentionally designed for cross-sell, repeat purchase, or lead nurturing.
Retargeting tests can compare intent stage, lookback window, message, or offer, but not all at once. For example, to test a 7-day cart audience against an 8-to-30-day cart audience, keep the ads and offer constant. To test urgency messaging against educational messaging, use the same eligible audience and change only the message. Small retargeting pools may not deliver enough conversions for reliable testing, so consolidate stages when necessary rather than creating many underfunded ad sets.
Measure Results and Make Decisions
Select a primary metric aligned with the business outcome. For ecommerce, this may be new-customer cost per purchase or new-customer return on ad spend. For lead generation, cost per lead is incomplete if lead quality differs, so include qualified-lead rate, cost per qualified lead, and eventual customer acquisition cost when the data is available. Supporting indicators such as click-through rate, landing-page-view cost, conversion rate, frequency, and reach help diagnose performance but should not replace the primary metric.
Do not declare a winner after a small number of conversions or one unusually strong day. Allow enough time to cover normal weekday variation and accumulate meaningful outcome volume. The required volume depends on conversion frequency, expected difference between cells, and business risk; there is no universal spending amount that guarantees certainty. Avoid frequent edits because budget, audience, creative, or optimization changes can disrupt delivery and invalidate the original comparison.
Interpret scale as well as efficiency. One audience may produce the lowest acquisition cost but only spend a small amount or reach a narrow population. Another may be slightly less efficient but capable of generating substantially more qualified customers. The decision can therefore be to keep the efficient audience as a limited layer while using a scalable audience for growth. Retargeting should also be evaluated for incremental value, not only high attributed return, because many warm users may have converted without another advertisement.
At the end of the test, classify the result as winner, loser, or inconclusive against the prewritten rule. A winner is ready for a controlled budget increase or a confirmation test. A loser should be paused unless the diagnostic data identifies a correctable issue outside the tested variable. An inconclusive result should not be presented as proof of equality; it may require more volume, a larger audience difference, or a simpler test design.
Common Failure Modes and Operating Checklist
The most common failure is variable contamination. Different creative, budgets, offers, landing pages, attribution settings, or optimization events make an audience comparison unreliable. Another failure is hidden overlap: prospecting includes recent visitors, multiple retargeting stages contain the same people, or customers remain eligible for acquisition ads. Review inclusions, exclusions, audience definitions, and delivery settings before launch rather than trying to repair the logic after spending begins.
Fragmentation is another frequent problem. Creating many small audience cells reduces delivery, increases volatility, and slows learning. Use the fewest cells needed to answer the business question. Confirm that each cell is large enough to deliver, that retargeting windows reflect the buying cycle, and that budget is proportionate to available audience size. Watch frequency in small warm audiences because rapid repetition can create fatigue even when attributed conversion metrics initially look strong.
A test is operationally ready when it has one hypothesis, one primary variable, comparable conditions, documented exclusions, a primary business metric, a planned duration, and a decision rule. Prospecting and retargeting results should be reported separately, then combined into a funnel-level view for budget planning. This approach does not eliminate uncertainty, but it produces evidence that a business can act on instead of a collection of disconnected campaign results.
Lesson Checkpoint
Review what you learned and get feedback on your work.