

How to Debug a Node.js API in Production
Start With a Reproducible Production Symptom
Production debugging begins with a precise symptom, not a guess about which function is broken. Record the affected endpoint, HTTP method, approximate start time, status code, response latency, deployment version, and whether the issue affects every user or only a segment. For example, “POST /api/orders returns 500 for European customers after release 2025.03.18” is much more useful than “the API is unstable.”
Compare the failing request with a successful request that uses similar inputs. Check whether the problem is consistent, intermittent, tied to one region, or limited to a particular account type. A short incident timeline helps connect symptoms to changes such as a deployment, database migration, environment-variable update, traffic increase, or third-party outage. This evidence narrows the search before you inspect application code.
Use Structured Logs in Node.js
Plain console messages are difficult to search when several production instances handle requests at the same time. Use structured logs with fields such as timestamp, level, service, environment, requestId, route, statusCode, durationMs, and error name. A logger such as Pino can emit JSON efficiently, allowing a log platform to filter all 500 responses or sort requests by latency without parsing sentences by hand.
Include context that helps explain the failure, but do not log passwords, access tokens, full payment details, or unrestricted request bodies. For an order failure, logging orderId, customer segment, database operation name, and dependency status may be enough. Use log levels consistently: info for important lifecycle events, warn for recoverable anomalies, and error for failures requiring investigation. Always include the original error stack in internal logs, because the stack usually identifies the exact source line and call path.
Trace One Request Across Services
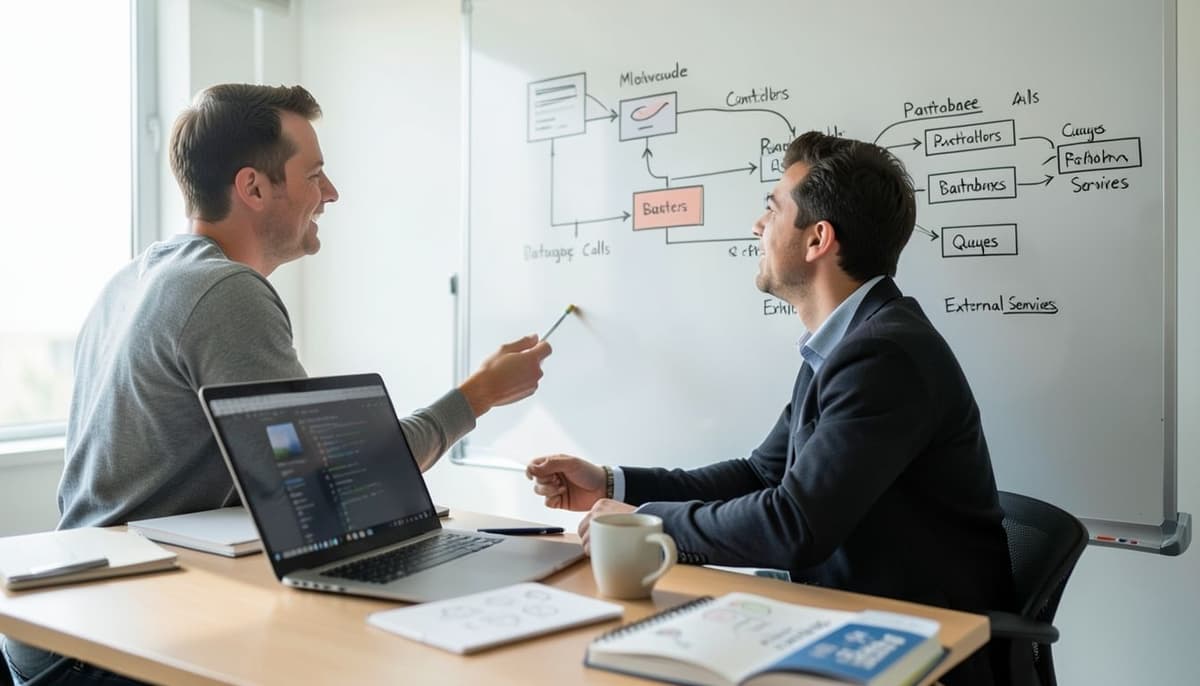
A request ID lets you follow one operation through middleware, controllers, database calls, queues, and external services. Generate an ID at the edge if the client did not provide one, attach it to the response header when appropriate, and pass it through downstream calls. In an Express application, request middleware can place the identifier on the request object or in an asynchronous context so later log statements use the same value.
For broader systems, use distributed tracing with OpenTelemetry and propagate trace context through HTTP requests. A trace can show that a 900 millisecond API response spent 40 milliseconds in Node.js, 700 milliseconds waiting for a database query, and 160 milliseconds calling a recommendation service. That breakdown prevents an application team from optimizing JavaScript code when the real delay is a dependency. Make sure traces are sampled and scrubbed according to your privacy and cost requirements.
Inspect Errors Without Breaking the Service
When an error reaches your error tracker, inspect the complete stack trace, error type, request context, and release identifier. Errors such as TypeError, JSON parse failures, database constraint violations, and timeout exceptions imply different investigation paths. Group repeated errors by normalized stack trace rather than by unique request data, otherwise one bug can appear as thousands of unrelated issues.
Avoid attaching a live debugger to a busy production process unless your platform supports controlled, low-overhead debugging. Breakpoints can pause event-loop work and increase latency for unrelated users. Prefer safe diagnostics such as stack traces, heap snapshots captured through an approved process, CPU profiles, and temporary debug logging with a defined expiration time. If you must enable additional logs, guard them with configuration, restrict their scope, and record exactly when the setting is turned off.
Check Event Loop and Resource Health
Node.js can serve many concurrent requests, but JavaScript work that blocks the event loop delays every request handled by that process. Look for synchronous file operations, expensive JSON processing, large regular expressions, image transformations, or loops over unexpectedly large arrays. Event-loop delay, CPU usage, request duration, and active handles together provide better evidence than CPU percentage alone. A process using moderate CPU can still have poor response times if callbacks are waiting behind a blocking operation.
Memory problems require a different approach. Compare heap usage after garbage collection, resident set size, restart frequency, and the number of active connections. A steadily rising heap may indicate retained objects, unbounded caches, listeners that are never removed, or request data stored beyond its lifetime. Confirm whether a memory increase is caused by the application or by a dependency before changing the container limit. A larger limit can postpone an out-of-memory failure without removing the leak.
Validate Databases and External Dependencies
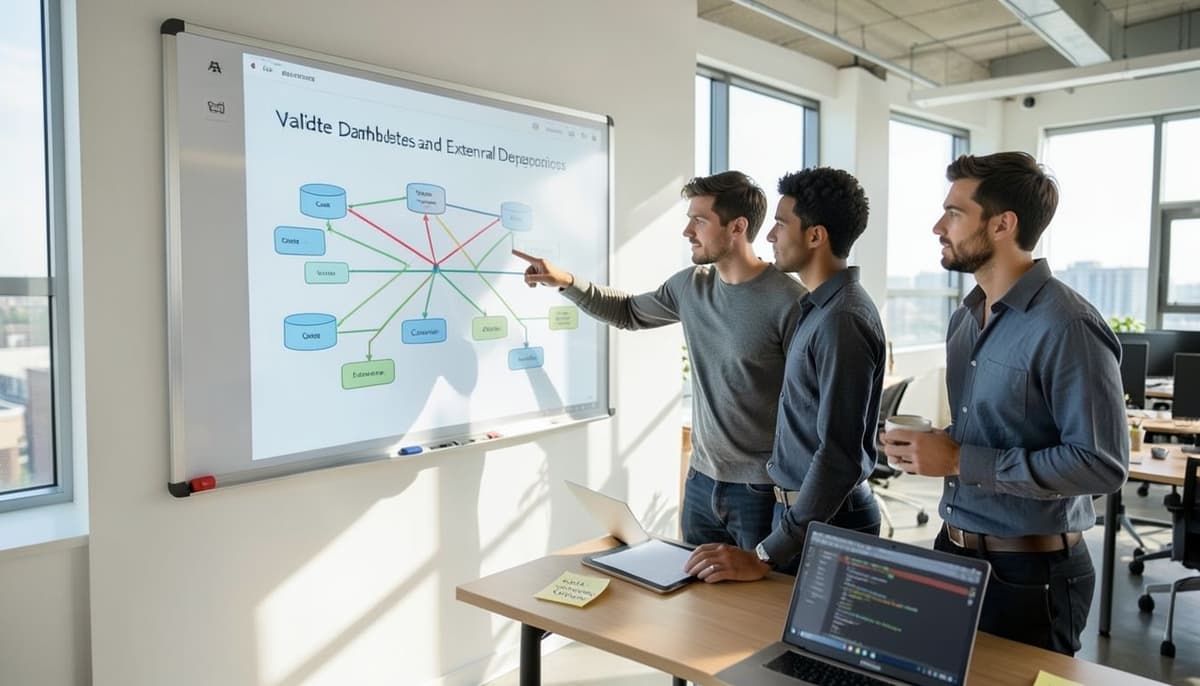
Many API incidents originate outside the route handler. Check database connection-pool usage, query duration, lock waits, failed transactions, slow-query logs, and recent schema changes. A pool exhausted by long-running queries can make new requests appear to hang, eventually producing timeout errors. Compare the exact query parameters and execution plan when possible, while protecting personal or confidential data in diagnostic output.
Treat external services as observable dependencies with explicit timeouts, retry limits, and circuit-breaking behavior where appropriate. A retry without a limit can multiply traffic during an outage and consume all available connections. Log the dependency name, operation, timeout value, attempt number, and resulting error category. For a payment provider returning 429 responses, the correct response may be controlled backoff and a queued operation rather than immediate repeated requests from every API worker.
Apply a Safe Fix and Verify Recovery
Choose the smallest reversible action supported by the evidence. Depending on the cause, that may mean rolling back a release, disabling a feature flag, correcting an environment variable, terminating a stuck worker, or adding a temporary rate limit. Preserve the failing request shape and relevant logs before making changes, because a rollback can remove the evidence needed for a later root-cause analysis. Never expose diagnostic endpoints or stack traces directly to unauthenticated users.
Verification should use production signals, not only a successful manual request. Watch error rate, p95 or p99 latency, throughput, event-loop delay, memory, dependency failures, and business-level outcomes such as completed orders. Test both the previously failing case and a normal case after the fix. Once the incident is stable, write a short timeline explaining the trigger, detection gap, contributing conditions, corrective change, and the monitor or test that will catch the problem earlier next time.
Related Articles
Further Reading
Tags :
- Web Development